comparisons
LangChain vs LlamaIndex: Production Verdict for 2026
LangChain vs LlamaIndex in 2026: LangChain for agent loops, LlamaIndex for retrieval-heavy RAG. Versioning, t…
How VectorStoreIndex embeds nodes, where text lives, why similarity_top_k defaults to 2, and how to persist, filter and update it in production.
Read the article →LangChain vs LlamaIndex in 2026: LangChain for agent loops, LlamaIndex for retrieval-heavy RAG. Versioning, t…
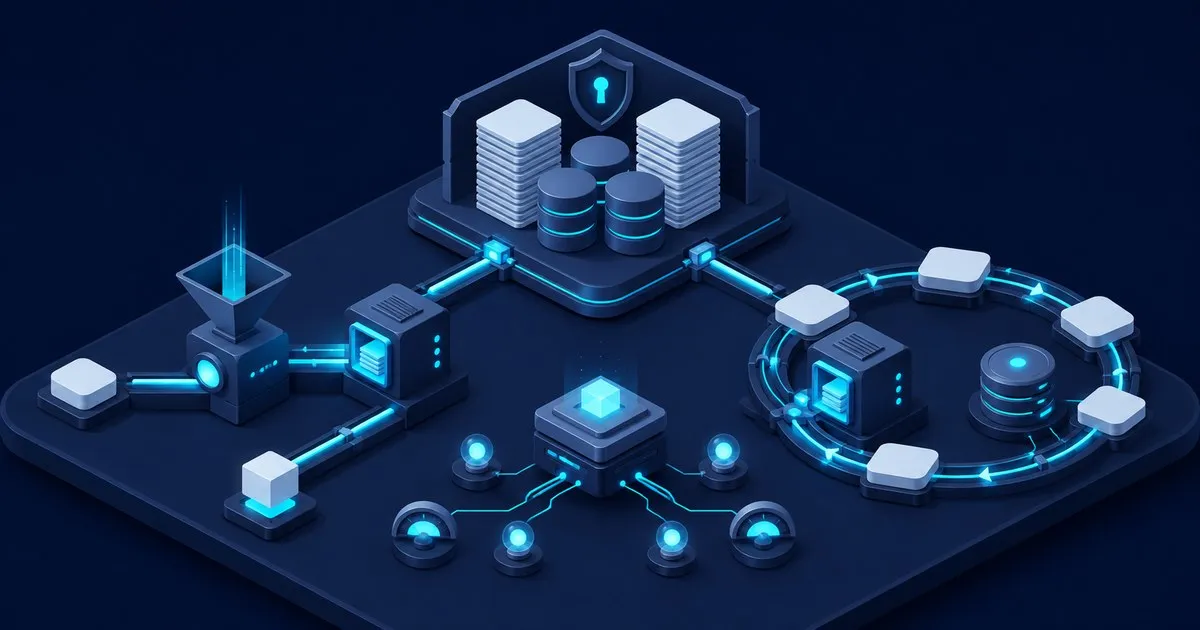
Choose the right LlamaIndex interface by comparing state, retrieval behavior, latency, evaluation, and deploy…
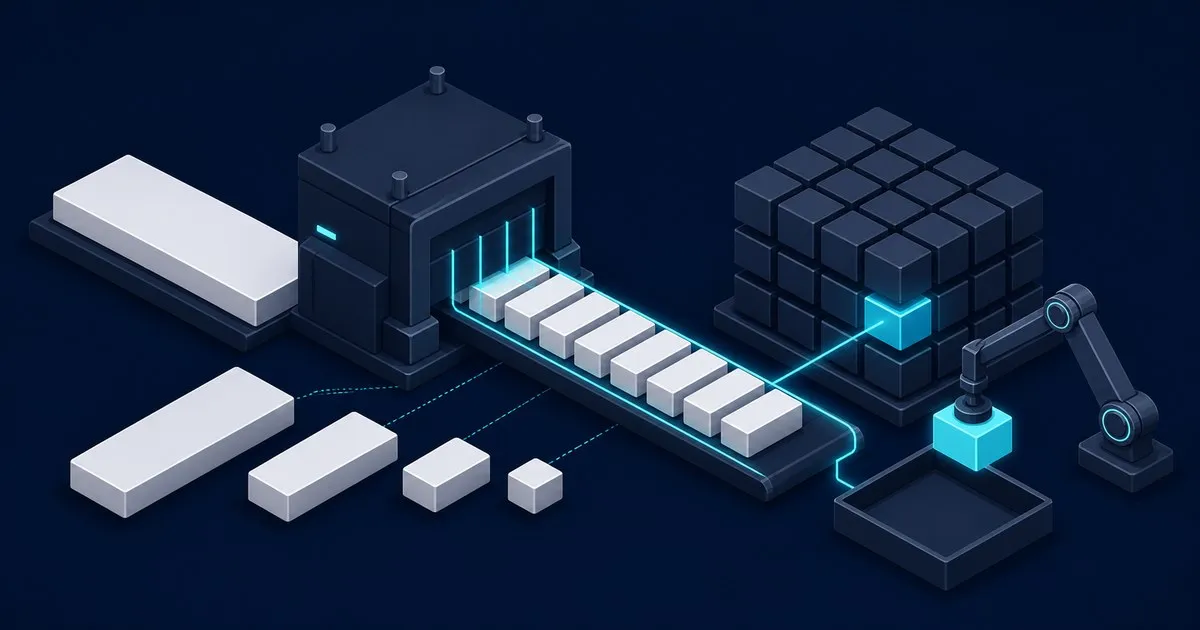
Configure LlamaIndex chunk_size and chunk_overlap with SentenceSplitter, per-index transformations, and a rep…
A documentation-based comparison of LlamaIndex and LangChain for retrieval: what each project optimises for, …
Nine failure modes in LlamaIndex retrieval, how to tell them apart from source nodes and scores, and the docu…
Install LlamaIndex, index a folder of documents, query it, persist the index, and swap in a real vector store…
A reading order for LlamaIndex retrieval, from what the pipeline is doing to what to change when the answers come back wrong.
How documents become nodes, and which index type answers which kind of question.
Install, index a folder, query it, persist it, and move to a real vector store.
What LlamaIndex and LangChain each optimise for, and why the switch is cheaper than it feels.
Nine retrieval failure modes, told apart from the source nodes and scores.
Sizing an index before you provision anything? Use the chunking and vector store sizer to turn corpus size, chunk size and embedding dimensions into a chunk count and a RAM figure.